Heura Eval 004: Arche 0.19 vs 0.20 vs 0.21
Download the full report (PDF)
Arche 0.21 is much better on the business benchmarks and about the same as 0.20 in Heura Studios. It more than doubles both business benchmarks (v1 89.2%, v2 68.3%, before the code checks) and keeps nearly all of 0.20’s learning from taught answers (GEN-1 45/68). It practised these 16 task types, so the checks still to come (the code checks, BIZ-FRESH and CODE-1) will show how far the jump carries.
In the Studio it gains the most from training (the Trailhead exam goes from 62% to 88%, level with 0.20) and scores 2 of 6 on the two hard customer questions before and after training (0.20: 3, then 1). One Fix still carries over (S1b 3/3).
Scorecard
0.21 is far ahead on both business benchmarks and within one case of 0.20 everywhere else.
| Measure | Arche 0.19 | Arche 0.20 | Arche 0.21 | 0.21 vs 0.20 |
|---|---|---|---|---|
| Business AI Benchmark v1 (20 tasks) | 29.2% | 33.3% | 89.2% | Better |
| Business Extension v2 (20 tasks) | not run | 32.8% | 68.3% | Better |
| GEN-1: learn from one taught answer (68) | 32/68 | 46/68 | 45/68 | Within 1 case |
| Picks the right tool (30 tasks) | 30/30 | 30/30 | 29/30 | Within 1 case |
| Studio check, unseen hotel (10) | 10/10 | 10/10 | 10/10 | Same |
| Trailhead exam, untrained (8) | 88% | 75% | 62% | Within 1 case |
| Trailhead exam, after training (8) | 75% | 88% | 88% | Same |
| S1 + S2 before training (of 6) | 2/6 | 3/6 | 2/6 | Within 1 case |
| S1 + S2 after training (of 6) | 2/6 | 1/6 | 2/6 | Within 1 case |
| S1b after one Fix (of 3) | 3/3 | 3/3 | 3/3 | Same |
| Verity, untrained on this base (9) | not run | 4/9 | 4/9 | Same |
| Verity, trained on this base (9) | 2/9 | 3/9 | 4/9 | Within 1 case |
The business scores are the mean of 3 runs, before the code checks. With them, 0.19 scored 27.5% and 0.20 33.3% on v1; 0.21’s aren’t scored yet, and neither are v2’s sandboxed code checks. The Trailhead and S rows come from our Studio protocol (below). Verity is an assistant Ryan built in the Studio, asked 9 held-out questions.
What changed in 0.21
0.21 is 0.20 trained one more epoch on new business and coding rows, plus a replay of 0.20’s data.
- Trained on Kaggle (two T4 GPUs) from 0.20: 5,713 rows, 1 epoch, 714 steps, learning rate 1e-4. Loss fell from about 0.80 to under 0.1. The run, with its benchmarks, took 2 hours.
- 1,600 rows of business work: the 16 task types of the two business benchmarks (complaints, campaigns, sales, expenses, launches, policies, invoices, reorders, ticket routing, approvals and more), 100 new variants each, half of them advanced. Every answer comes from a solver that also reproduces both benchmarks’ answer keys; no row copies a benchmark case.
- 1,520 coding rows whose code passed its own tests in a sandbox, 895 MBPP problems, and 1,698 rows replayed from 0.20’s training so it keeps what it had.
Business benchmarks
0.21 more than doubles both business benchmarks overall, and on the advanced cases of both it roughly triples 0.20’s score.
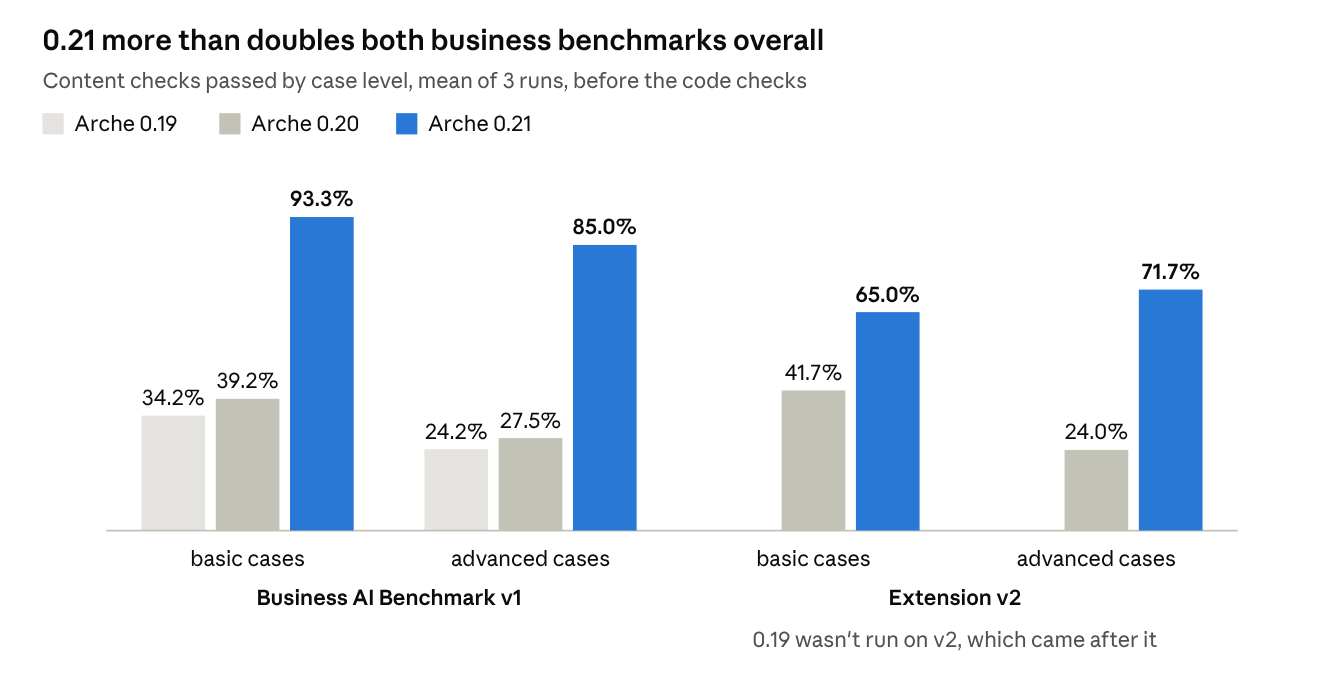
0.21 practised all 16 task types with new facts, so these scores measure skill on practised types. Its code checks aren’t scored yet (0.19 and 0.20 passed none of v1’s four). BIZ-FRESH’s 36 new cases of the same types will show whether the jump holds on new facts, and CODE-1’s unpractised part and HumanEval whether it carries to new kinds of tasks.
Learning from one taught answer
0.21 kept nearly all of what 0.20 learned: 65 of GEN-1’s 68 cases scored the same, and every group is within one case. GEN-1 asks about companies, words and puzzle numbers never seen in training, each with one taught example in the Studio brief.
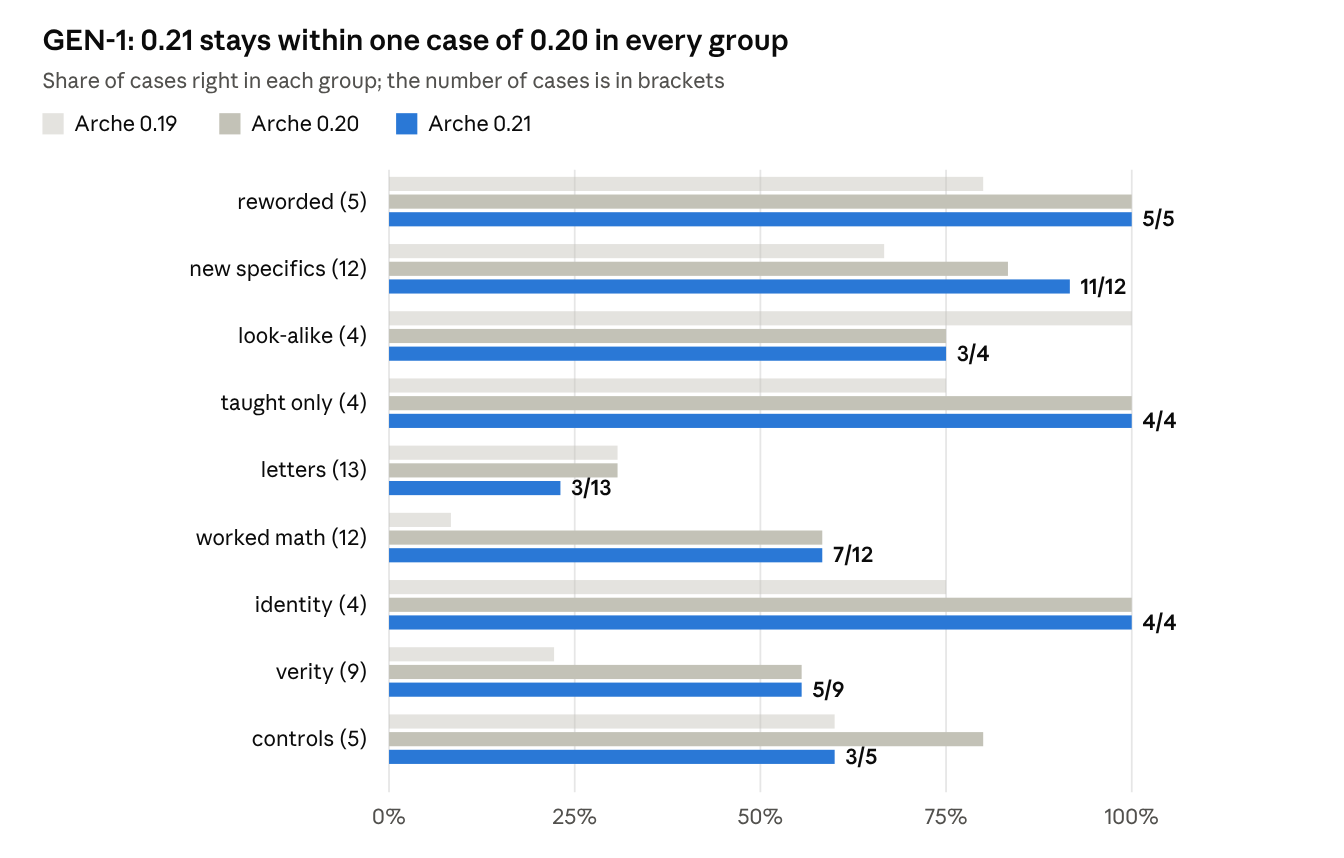
Of the three cases that changed from 0.20, 0.21 gained one (what time the pool closes on Saturday) and lost two (the f’s in coffeehouse, and a price floor 0.20 had right). Counting the s’s in possessive fails on every version.
What we saw in the Studio
We ran the protocol of Evals 001 to 003 in a throwaway copy of Heura Studios: a new support assistant for a made-up outdoor store (Trailhead, from the Customer Support kit), two hard customer questions (S1 and S2), the kit’s exam, training on the kit’s 10 examples, then one Fix and a follow-up question (S1b). Claude scored the answers with Eval 001’s rubric: the right policy or source, no invented facts or promised actions, every part covered.
In the Studio, 0.21 often stops at the first half of an answer, and twice it copied a taught example instead of answering.
- Half answers. Two of its untrained exam answers are true but incomplete, so they count as misses. “Sorry, no. Express shipping isn’t available to P.O. boxes.” never says standard shipping works, and its Care answer drops the 30 days to add it.
- S1 says no outright. “The tent has been over the 30-day window … so it’s outside our return window.” The Refund Policy gives store credit from day 31 to 60, and a snapped pole belongs to the warranty, which 0.21 never mentions.
- S2 is kinder but less useful. “I’m sorry for the frustration. I don’t have that information.” It is the only S2 that apologizes, but it never answers the request for a manager; 0.19 and untrained 0.20 said plainly they couldn’t connect one.
- It copies taught examples. After training, its S1 answer is the kit’s gift-card example nearly word for word. On a sequence puzzle it repeats the taught example’s numbers and that example’s answer, 206 (the right answer is 136).
- Training and the Fix still work. The kit’s 10 examples lifted its exam from 62% to 88%, and the trained version went live. One Fix carried over to S1b with every detail traceable.
S1 fails on every version for the reason Evals 001 to 003 found: its brief gets the Shipping FAQ and the Refund Policy, never the Warranty doc.
Limits of this run
- Greedy decoding and one run per case for GEN-1, the protocol and Verity: differences of 1 or 2 cases are noise, and each exam question is worth 12.5 points.
- 0.21’s benchmarks ran on Kaggle, 0.19’s on a Mac. 0.20 ran in both places and scored the same (GEN-1 46/68, v1 33.3% before the code checks).
- The business numbers are before the code checks, on task types 0.21 practised with new facts.
- Claude scored the protocol and Verity answers, as in Evals 001 to 003. Read strictly, 0.21 would score 1 of 6 on S1 and S2, before and after training.
Next
- Score the rest of the run: v1’s code checks, v2’s sandboxed code, CODE-1 and BIZ-FRESH, which shows whether the jump holds on new facts.
- Keep the Studio voice in 0.22, with more Studio rows from other companies whose answer needs its second half: the alternative, the middle tier of a rule, the escalation.
- Fix retrieval for long questions, so the Warranty doc reaches S1’s brief.